Tutorials Concordance
Concordance searches one or two Data Blocks for a word or phrase and shows each match in context. It is useful for comparing how terms are used and where they appear within documents.
Add up to two Data Blocks and choose the source text column for each one. A fresh selector initializes that choice from the Data Block's saved Document Column Preference when it has one.
Enter the word, phrase, or token alternatives to find. Each result includes the left context, matched text, right context, and any source metadata columns you choose to display.
- Text searches the original text column. Whole-word, regular-expression, and case-sensitive options apply in this mode.
-
Tokens performs exact-token matching. Separate alternatives with spaces,
commas, or
|.
Running Tokens mode requires a tokenizer model for every selected Data Block. The selector saves each model as that Data Block's Tokenizer Preference, separately from its Document Column Preference. A fresh Concordance Analysis always starts in Text mode, including when every selected Data Block already has a saved model or you arrive from Token Frequency. Select Tokens mode explicitly to enable the tokenizer selectors, then choose or confirm a model for each source.
Preview records the exact source columns, tokenizer mapping, and search mode in the immutable Analysis request. Reopening an existing Preview Analysis uses those saved values even if the current Data Block preferences have since changed.
In Text mode, enable Use Regular Expression for pattern matching.
| Pattern | What it matches |
|---|---|
child(ren)? |
child or children |
tax|budget|welfare |
Any one of the three words |
#\w+ |
Any hashtag |
\w{2}-\d{4,6} |
IDs such as SA-3988 or id-4589 |
Use regexr.com to test unfamiliar patterns. Whole Word excludes partial-word matches, and Case Sensitive keeps letter case distinct.
Left context and Right context control how many tokens appear around a match. Both default to 10 and accept values from 0 to 50. In Text mode, Ignore punctuation is on by default: punctuation and symbol-only tokens do not consume those counts or become L1/R1, but the original punctuation and whitespace remain visible in each context. This option does not change which text or regular-expression matches are found. Tokens mode already applies its tokenizer's punctuation filtering and does not show this option.
Concordance Preview is document-paged. Documents per page controls how many source documents the current page evaluates: 10, 20, 50, 100, 200, 400, or 800. A page can contain fewer visible rows because documents without a match are omitted, while a document with several matches contributes several rows.
The footer reports the matches and matching documents found after processing the current source-document batch. An empty page does not mean later pages are empty.
Click Preview to create a durable Preview Analysis. The label always remains Preview. After success, changing an execution parameter enables Preview again; reverting exactly to its submitted request disables it. Preview and Run All keep independent submitted-request baselines. Each page navigation or sort request recomputes that page from the retained input snapshot. Preview pages are not retained or reused.
Preview pages, page sizes, and source-metadata sorts are fresh projections over the retained snapshot. They never read the current mutable Data Block, so editing a source cannot silently change that Preview Analysis.
In separated Preview tables, selected source metadata headers are sortable. Generated scalar headers such as matched text, L1/R1, frequencies, and offsets show Run All to enable sorting because Preview has not materialized the whole Result. Full document and left/right context strings stay unsorted.
Table view shows one row per match. Click a row to inspect the full source document and its metadata. Use the metadata selector to add source columns to the table.
L1 (CONC_l1) is the token immediately left of the match and R1
(CONC_r1) is the token immediately right. Their frequency columns count each
value across the complete Run All Result. The matched-text cell always uses
strong source-colour emphasis. The last exact, case-sensitive L1 occurrence in
the left context and the first R1 occurrence in the right context use a softer
source-colour tint. Empty or unmatched anchors remain plain. Turn off
Highlight L1/R1 in context to hide only those inline tints for the current
tab session. The direct L1/R1 cells remain plain and available for sorting,
frequencies, export, and Data Block Creation.
Dispersion view groups the current page by source document. Vertical marks show the relative position of each match within the document. Bar length proportional to text length scales bars by document length; with it off, all bars use the same width for easier positional comparison.
Match markers and dispersion series use the colour assigned to their exact, case-sensitive matched text. Colours come from the sorted union of term labels for the Result and remain stable when terms are hidden.
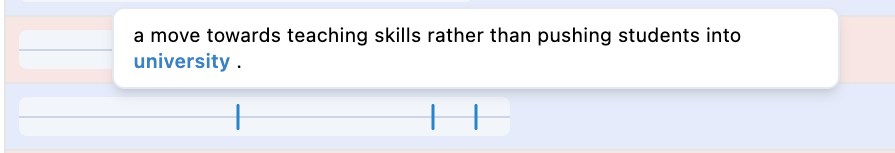
Hover over a match line to see its immediate left context, matched text, and right context.
When proportional bar length is off, the chart shows one series for each exact matched term across relative-position bins. Preview derives its static legend from the current page. Review uses whole-Result density, so changing the table page does not change the chart.
Choose Line, Bar, or Area. This presentation choice applies to the dispersion blocks in the current session. Bar charts use side-by-side series with alternating bin backgrounds at 4, 5, or 10 bins. At 20, 25, 50, or 100 bins, the series stack into one bar per bin so the bars remain visible. Other chart types are unchanged by the selected bin count.
Bin No. divides the 0–100 % document range into 4, 5, 10, 20, 25, 50, or 100 buckets. Changing the count clears selected bins so an old bin index is not reinterpreted under new boundaries.
In Review, click anywhere inside the plot to select the bin nearest the vertical
axis pointer; Shift-click another bin to extend
the range. Clear Selection removes the bin filter. Click a legend term to
hide or show it. Visible terms intersected with selected bins control the
displayed documents, match markers, legend counts, and Concordance Document
Data Block Creation.
Documents without a surviving match disappear. Preview has a static legend and
does not apply these filters. Select Uncased beside a chart legend to merge
case variants into one series, colour, and summed legend count; for example,
jobs (35) and Jobs (2) become jobs/Jobs (37). This checkbox is shared by
all separated charts and Combined View. Changing it restores all hidden legend
terms while preserving selected bins.
Download the current chart as PNG, SVG, or JPEG. The export includes the visible term series, complete legend with hidden-state indication, and active bin and term-filter summary.
Enable Show metadata and select source columns to display beside matches. With two Data Blocks, common columns and source-specific columns are grouped and colour-coded. Generated Concordance fields are already part of the Result and do not become source-metadata sort keys.
With two Data Blocks, Separated gives each source its own Result block and sort state. Combined interleaves the current pages and colours rows by source. Combined headers are display-only because one sort order cannot be applied independently to both source snapshots.
In Separated mode, each source has independent hidden terms and selected bins. In Combined mode, one frontend-only filter is applied separately to both source Results before their pages are interleaved. Terms, rather than sources, remain the chart series.
Run All can be started before or after Preview. It submits one thin Run All group with one independent Supporting Analysis per selected source. Each child uses the Run All request's immutable snapshot and tokenizer mapping and retains one complete table Result. Run All does not add Data Blocks to the Workspace.
After success, Review reads each immutable Result through explicit match and document projections. Table View always shows Matches per page. Dispersion View always shows qualifying Documents per page; filtering occurs before sorting, counting, and paging, and the selected page size applies independently to each source. Review has no page-local Found summary.
Separated Review Table View can sort selected metadata, matched text, L1/R1, their frequencies, and start/end offsets across the complete materialized Result. Sorting is case-sensitive and uses Polars' default null ordering. Equal values have no guaranteed secondary order. The document and full context headers remain plain, and combined Review remains unsorted.
The Review density chart always summarizes the complete immutable Result, not
the visible page. CONC_dispersion remains a frontend presentation field and
is never stored or queried as a physical Result column.
Use Add to Workspace to create Derived Data Blocks after reviewing the
Result. Table View creates a Concordance Match Data Block Creation, with one row per
match and the current flat selected-column behavior. Dispersion View creates a
Concordance Document Data Block Creation, with one row per qualifying original
source row. It contains the required original document, required
CONC_extraction (surviving KWIC extractions joined with plain newlines), and
optional metadata. The document and extraction columns are locked on and
metadata starts off. Every source is checked by default; unchecking a source
hides but retains its controls, and at least one source must remain checked.
For multiple sources, enable Sync columns to limit optional choices to exact,
case-sensitive column names shared by every checked source. Existing shared
selections are combined when Sync columns is enabled, and individual changes or
Select all and Select none then apply to every checked source. Unchecked
sources keep their independent selections. Required document and extraction
columns remain locked on and are not synchronized. If fewer than two sources
remain checked, Sync columns turns off automatically.
Submitting the checked sources is atomic, including when a source has no
qualifying rows and therefore creates a schema-only Data Block.
The Tab keeps its complete Analysis forest. Clear Results removes that forest. Preview or Run All locks every parameter only while submission or execution is active; Stop becomes available once the task exists. If either root fails or is cancelled, parameters unlock but both execution actions stay disabled until Clear Results.
| Symptom | Likely cause | What to try |
|---|---|---|
| No results on one page | The current source-document batch has no match | Continue to the next page |
| Tokens mode is unavailable | At least one selected Data Block has no source column | Select a source text column for every input |
| Too many partial matches | Whole Word is off in Text mode | Enable Whole Word |
| A regular expression fails | Invalid pattern syntax | Test the pattern on regexr.com |
| A generated Preview header does not sort | Whole-Result generated sorting requires materialized matches | Run All, then sort the separated Review table |
| Run All is disabled | Inputs are incomplete or another Run All is active | Complete the inputs or wait for the active Analysis |
| Preview differs from the edited Data Block | You reopened a historical Preview Analysis | Change an execution input and choose Preview to capture a new snapshot |
| Setting | Default | Notes |
|---|---|---|
| Search mode | Text | Select Tokens explicitly to enable tokenizer selection |
| Left / Right context | 10 tokens each | Range 0–50 |
| Whole Word | Off | Text mode only |
| Regular expression | Off | Text mode only |
| Case Sensitive | Off | Text mode only |
| Ignore punctuation | On | Text mode only; punctuation remains visible but does not consume context tokens |
| Documents per page | 20 | Controls source documents evaluated per Preview page |
| View | Table | Returning to Concordance starts in Table View |
| Highlight L1/R1 in context | On | Local table-display state; matched text remains emphasized when off |
| Bin No. | 20 | 4, 5, 10, 20, 25, 50, or 100 |
| Chart type | Line | Line, Bar, or Area |
| Review term visibility | All terms | Exact, case-sensitive labels |
- Select a Data Block and Preview a Text-mode Whole Word search.
- Compare two source-metadata sort orders.
- Switch to Preview Dispersion and compare the per-term series.
- Run All, open Review Dispersion, hide a term, and select a bin range.
- Compare Concordance Match Data Block Creation from Table View with Concordance Document Data Block Creation from Dispersion View.
- Change an execution input, then choose Preview to compare the new request deliberately while the earlier Result remains bound to its snapshot.